Search This Blog

Tuesday, January 30, 2024

Get SQL Server Data and Log File Folders (T-SQL Script)

Get SQL Server Data and Log File Folders (T-SQL Script)

The script below includes an extended comments section at the top that explains its features, how it works step by step, the permissions it needs, and its known limitations. It also explains why xp_create_subdir is the preferred way to create the folders, even though the script also generates Windows PowerShell and bash commands. Since the script documents itself in that much detail, I won't repeat it in this article. The comments are the best reference. Please read them before running the script, especially the testing notes: the script has had limited testing and hasn't been tested in some of the edge cases or rare configurations.

SQL Script:


/*****************************************************************************************
 Script  : Get SQL Server Database File Folder Locations
 
Purpose :
Returns a DISTINCT list of folders that must exist before database files
can be created or restored on an instance with the same layout (for example, when building a DR server, a migration target, or a restore destination). Supports: SQL Server 2005 and later on Windows; SQL Server 2017 and
later on Linux.
SQL Server 2000 is NOT supported. ----------------------------------------------------------------------------------------- FEATURES ----------------------------------------------------------------------------------------- * Reads every database's files from sys.master_files in a single query,
so offline,
restoring, and otherwise inaccessible databases are included. * Covers data (ROWS), transaction log (LOG), and FILESTREAM /
memory-optimized
container files (type 2). * Handles both Windows (backslash) and Linux (forward slash) paths. * Returns the PARENT folder of FILESTREAM / memory-optimized containers,
because
SQL Server requires the container folder itself to NOT exist
when it is created.
* Flags folders that hold a container (has_container_parent = 1) so
you don't
pre-create the container under them by mistake. * Generates ready-to-run commands for each folder: - check_if_folder_exists : T-SQL - EXEC master.dbo.xp_fileexist - xp_create_subdir : T-SQL - EXEC master.dbo.xp_create_subdir (PREFERRED method - see PREFERRED METHOD below) - os_create_folder : OS shell command, depending on the path type: * Windows paths -> Windows PowerShell command (New-Item -ItemType Directory -Force). Run it in a PowerShell window, NOT cmd.exe. * Linux paths -> bash command (mkdir -p). Provided as an ALTERNATIVE only. * Escapes single quotes in folder names so the generated commands stay valid. * Prints a warning when the caller lacks the permissions sys.master_files
needs to
return a complete result. ----------------------------------------------------------------------------------------- PREFERRED METHOD: xp_create_subdir ----------------------------------------------------------------------------------------- The script provides os_create_folder, but xp_create_subdir is the PREFERRED
way to
create the folders. Use os_create_folder only when xp_create_subdir
is not an option
(for example, you are not sysadmin, or the SQL Server
instance is not installed yet).
Why xp_create_subdir is preferred: * It creates the folder AS THE SQL SERVER SERVICE ACCOUNT, the same account that will later create, restore, and open the database files. If the command succeeds, you know that account can create folders at that location. * The service account becomes the folder's owner, so the folder will not end up owned by your personal or admin account. On Linux this matters most: a folder created with "sudo mkdir -p" is owned by root, and SQL Server (running as the mssql user) cannot write to it until someone runs chown/chmod. * os_create_folder runs as whoever opens the shell. A folder created that way may exist but still be inaccessible to SQL Server, and the failure only appears later when CREATE DATABASE or RESTORE fails with an "access denied" or OS error. * It runs from the same SQL session (SSMS, sqlcmd, or a SQL Agent job) as the restore or create, with no RDP or SSH logon to the server. * The same T-SQL command works on Windows and Linux instances. * Like mkdir -p, it creates any missing intermediate folders. Caveats: * xp_create_subdir is undocumented and requires sysadmin. * The service account still needs rights on the PARENT path. If it lacks them, xp_create_subdir fails. Treat that failure as a useful early warning, not something to work around with os_create_folder. ----------------------------------------------------------------------------------------- HOW IT WORKS ----------------------------------------------------------------------------------------- 1. Permission check: HAS_PERMS_BY_NAME tests for VIEW ANY DEFINITION, ALTER ANY DATABASE, and CREATE ANY DATABASE. sys.master_files does not raise an error when these are missing; it silently returns fewer rows. The script only warns; it does not stop. 2. Path separator detection (CTE f): A path starting with '/' is treated as Linux; everything else as Windows ('\'). 3. Trailing separator cleanup (CTE f2): Removes a trailing '\' or '/' so the next step strips the correct segment. 4. Folder extraction (CTE d): REVERSE + CHARINDEX finds the last separator, and LEFT keeps everything before it. - Data/log file : D:\Data\Sales.mdf -> D:\Data - Container : D:\FS\SalesFS -> D:\FS (the container's parent) 5. Deduplication and filtering (CTE g): GROUP BY returns each folder once. Drive roots (D:) and empty results (root-level Linux files) are excluded because they don't need to be created. 6. Command generation (final SELECT): Builds the check and create commands, escaping single quotes for T-SQL ('') and for bash ('\''). For Windows paths, os_create_folder contains a Windows PowerShell command, not a cmd.exe command. In PowerShell, single quotes are escaped by doubling (''). ----------------------------------------------------------------------------------------- REQUIREMENTS ----------------------------------------------------------------------------------------- * Running the query : VIEW ANY DEFINITION, ALTER ANY DATABASE, or CREATE ANY DATABASE (sysadmin has all three). * Generated xp_ commands : sysadmin. * Generated OS commands : An OS account with rights to create folders on the target. Windows paths: run os_create_folder in Windows PowerShell (or PowerShell 7) on the target server. Linux paths : run os_create_folder in a bash shell. Afterward, confirm the SQL Server service account has full rights on the new folders. ----------------------------------------------------------------------------------------- LIMITATIONS ----------------------------------------------------------------------------------------- * xp_fileexist and xp_create_subdir are undocumented and unsupported by Microsoft. They can change or be removed in a future release. * The xp_ commands run as the SQL Server service account, NOT as your login. That account needs NTFS/Linux permissions on the parent path. * Folders created with os_create_folder are owned by the account that ran the command, not the SQL Server service account. Permissions may need to be fixed before SQL Server can use them. * The script only GENERATES commands; it does not run them. Review the output before running it on the target server. * The output reflects THIS instance's file layout. Run it on the source, then execute the generated commands on the target. * The Windows os_create_folder command is Windows PowerShell syntax and will not work in cmd.exe. * Full-text catalog entries (type 4, SQL 2005-2008 R2) are excluded. * UNC paths (\\server\share\...), mount points, and symbolic links have not been specifically handled; results may need manual review. * On a case-sensitive server collation, folders that differ only by case (D:\Data vs D:\DATA) appear as separate rows, even though Windows treats them as the same folder. * Folder names ending in spaces may be trimmed, because LEN ignores trailing spaces. * Azure SQL Database and Azure SQL Managed Instance are out of scope; their file paths are managed by the platform. * The permission check warns but does not fall back to another method. ----------------------------------------------------------------------------------------- TESTING STATUS -- PLEASE READ ----------------------------------------------------------------------------------------- This script has gone through VERY LIMITED testing. It has NOT been tested in some edge cases or rare configurations, including but not limited to: - Folder names containing apostrophes, Unicode, or trailing spaces - UNC paths, mount points, or symbolic links Validate the output in a non-production environment before relying on it. Use at your own risk. ******************************************************************************************/ SET NOCOUNT ON; IF ISNULL(HAS_PERMS_BY_NAME(NULL, NULL, 'VIEW ANY DEFINITION'), 0) = 0 AND ISNULL(HAS_PERMS_BY_NAME(NULL, NULL, 'ALTER ANY DATABASE'), 0) = 0 AND ISNULL(HAS_PERMS_BY_NAME(NULL, NULL, 'CREATE ANY DATABASE'), 0) = 0 PRINT 'WARNING: Missing VIEW ANY DEFINITION / ALTER ANY DATABASE / CREATE ANY DATABASE. ' + 'sys.master_files may return incomplete results.'; ;WITH f AS ( SELECT mf.type, sep = CASE WHEN mf.physical_name LIKE N'/%' THEN N'/' ELSE N'\' END, p = mf.physical_name FROM sys.master_files AS mf WHERE mf.type IN (0, 1, 2) -- ROWS, LOG, FILESTREAM/memory-optimized ), f2 AS ( -- strip any trailing separator SELECT type, sep, p = CASE WHEN RIGHT(p, 1) = sep THEN LEFT(p, LEN(p) - 1) ELSE p END FROM f ), d AS ( -- parent folder (for type 2 = container's parent) SELECT type, sep, folder_path = LEFT(p, LEN(p) - CHARINDEX(sep, REVERSE(p))) FROM f2 WHERE CHARINDEX(sep, p) > 0 ), g AS ( SELECT folder_path, sep, has_container_parent = MAX(CASE WHEN type = 2 THEN 1 ELSE 0 END) FROM d WHERE folder_path <> N'' AND folder_path NOT LIKE N'_:' -- skip drive roots GROUP BY folder_path, sep ) SELECT folder_path, has_container_parent, -- 1 = do NOT pre-create the container under it check_if_folder_exists = -- T-SQL N'EXEC master.dbo.xp_fileexist N''' + REPLACE(folder_path, N'''', N'''''') + N''';', xp_create_subdir = -- T-SQL - PREFERRED (runs as SQL Server service account) N'EXEC master.dbo.xp_create_subdir N''' + REPLACE(folder_path, N'''', N'''''') + N''';', os_create_folder = -- ALTERNATIVE only (runs as the shell user) CASE WHEN sep = N'/' -- Linux path: bash command THEN N'mkdir -p ''' + REPLACE(folder_path, N'''', N'''\''''') + N'''' -- Windows path: Windows PowerShell command (do NOT run in cmd.exe) ELSE N'New-Item -ItemType Directory -Force -Path ''' + REPLACE(folder_path, N'''', N'''''') + N''' | Out-Null' END FROM g ORDER BY folder_path;


Use Cases:

Knowing where SQL Server keeps its database files is useful for many day-to-day DBA tasks. The most common reason is simple: when SQL Server needs to create a file in a folder that doesn't exist, the operation fails. Knowing the folder layout ahead of time lets you build it before that happens.

Backup and Restore

  • Restores to another server: When you restore a database, SQL Server recreates each file at its original path unless you redirect it with WITH MOVE. If that folder doesn't exist on the target server, the restore fails. Knowing the source folder layout lets you either create the same folders first or plan the WITH MOVE paths.
  • Backup destinations: Backups should not live on the same disk as the database files. If that disk fails, you lose the database and its backups together. Knowing where the data and log files live helps you choose a separate backup location.

High Availability and Disaster Recovery

  • Adding an availability group replica: With automatic seeding on SQL Server 2016 and earlier, the folders must already exist on the new replica and match the primary's paths. SQL Server 2017 and later can work with different paths, but Microsoft still recommends matching them. With manual seeding, you can redirect files with WITH MOVE.
  • Adding files later: Matching folders matter after setup too. If someone adds a data or log file on the primary to a path that doesn't exist on a secondary, the add succeeds on the primary, but the secondary database is suspended and stops synchronizing. Log shipping secondaries hit a similar problem when they restore that log backup.
  • DR planning: A DR plan needs more than backups. It needs a target server with the right drives and folders ready, so you aren't building the layout during an outage.

Server Builds, Rebuilds, and Migrations

When you build a replacement server, do a side-by-side upgrade, or migrate databases, the folder layout is part of the environment you're reproducing. You can either recreate the same structure or deliberately design a better one. Either way, you need to know what exists today.

Capacity Planning and Performance

  • Disk space: Mapping files to their volumes shows which drives are filling up and helps you forecast growth before a full disk stops the database.

  • File placement: Data files, log files, and tempdb have different I/O patterns. Knowing where each one lives helps you spot problems, such as logs sharing a disk with data files, and plan moves to faster or less busy storage.

Security, Auditing, and Exclusions

  • Compliance: Internal policies or regulations may require database files to sit on encrypted or approved storage. The folder list is what you audit against.

  • Antivirus and file-level backup exclusions: Security and backup teams usually need the exact data, log, and backup folders. Antivirus scanning of active database files can hurt performance or cause file access errors. File-level backup agents that copy open .mdf/.ldf files don't produce usable database backups.

Troubleshooting

Errors such as "operating system error 3 (The system cannot find the path specified)" or "access denied" during file creation, restore, or startup point straight at a folder. Knowing the expected paths helps you quickly check whether the folder exists and whether the SQL Server service account has permissions on it.

Automation and Tooling

Scripts for backups, file-growth monitoring, storage policies, and server builds often need to know where database files live. Some, like the script in this article, also generate the commands to create those folders on another server.


Understanding and Using xp_sqlagent_enum_jobs in SQL Server

Understanding and Using xp_sqlagent_enum_jobs in SQL Server

What is xp_sqlagent_enum_jobs?


xp_sqlagent_enum_jobs is an undocumented, extended stored procedure in Microsoft SQL Server. It is used to provide information about the jobs that are currently managed by the SQL Server Agent. This extended stored procedure is used in some internal procedures (e.g. sp_get_composite_job_info) by SQL Server, but it can also be used in custom scripts or applications to obtain details about SQL Agent jobs, especially in automated scripts or applications that need to track job status or performance. For example:


How to start SQL Server job using TSQL and wait for it to complete?


Often, the main impetus for using xp_sqlagent_enum_jobs is to programmatically check if a SQL Server Agent job is currently running, and then either wait for it to complete or take some other action. While interactive tools are available for monitoring job status, there aren't many reliable and well-documented stored procedures, system tables, or DMVs suitable for use in automated, non-interactive scenarios.


Syntax and Usage:


xp_sqlagent_enum_jobs typically requires that minimum two input parameters are given and, a third optional parameter. However, since this procedure is undocumented, the exact nature and behavior of these parameters might vary slightly based on the version of SQL Server. Here is a general explanation of its parameters:

  • Visibility Flag / is_sysadmin (Int): This parameter is usually an integer 0 or 1 to indicate if the executing user is a sysadmin (member of sysadmin role) and determines the scope of the job information returned by the procedure. A value of 1 indicates Yes and the procedure can return information for all jobs. A value of 0 means No in which case the procedure will return only those jobs that are owned by the executing user or jobs that the user has been granted permissions to view. 

In my experience though, xp_sqlagent_enum_jobs  seems to accept not only 0 or 1 but various integer values, both positive and negative.


  • Job Owner (Sysname): This is a string parameter representing the user in the context of whom the job information is requested. It's often provided in the format of a domain and username (e.g., DOMAIN\Username) or 'sa' if a DBA is running this procedure. This parameter is used along with the the visibility flag to determine which jobs are visible to the specified user based on their permissions.

Again in my experience, xp_sqlagent_enum_jobs  seems to accept any value, including invalid or non-existent usernames.

  • Job ID (UNIQUEIDENTIFIER): Optional parameter to get information for a single job with a specific job ID. 

If you are getting Job ID value from the msdb.dbo.sysjobs table, make sure to convert its value to a UNIQUEIDENTIFIER data type.


Basic Examples:


In this example, 1 is the visibility flag, and 'sa' represents the user.
EXEC master.dbo.xp_sqlagent_enum_jobs 1, 'sa' 


To get information about a specific job:


DECLARE @job_name NVARCHAR(100) = 'DatabaseIntegrityCheck - USER_DATABASES'
DECLARE @job_id UNIQUEIDENTIFIER
SELECT @job_id = job_id FROM   msdb..sysjobs WHERE  NAME = @job_name
EXEC master.dbo.xp_sqlagent_enum_jobs 1, 'sa', @job_id 


When using xp_sqlagent_enum_jobs, consider the following:


Permissions: The actual jobs returned can depend on the permissions of the user executing the procedure or the user specified in the parameters.

Security Risk: As an undocumented feature, using this procedure can pose a security risk, especially if used improperly or without understanding its impact.

Version Dependence: The behavior and availability of xp_sqlagent_enum_jobs can change without notice in different versions of SQL Server.

Results/Output Columns:


The procedure returns a result set with various columns providing details about each job. These details typically include:

  1. Job ID: A unique identifier for each job.
  2. Last Run Date: The date and time when the job was last executed.
  3. Next Run Date: The date and time when the job is scheduled to run next.
  4. Next Run Schedule ID: The identifier of the schedule according to which the job will run next.
  5. Requested To Run: Indicates whether the job has been requested to run immediately (outside its scheduled times).
  6. Request Source: Indicates the source of the run request.
  7. Request Source ID: The identifier of the request source.
  8. Running: Indicates whether the job is currently running.
  9. Current Step: The current step number the job is on (if it's a multi-step job).
  10. Current Retry Attempt: The number of the current retry attempt (in case the job is configured to retry on failure).
  11. State: The current state of the job.


What does it mean that xp_sqlagent_enum_jobs is undocumented?


xp_sqlagent_enum_jobs is indeed an undocumented extended stored procedure in Microsoft SQL Server. This means that it is not officially documented or supported by Microsoft in their public documentation. In essence, this raises several important considerations:

  • Lack of Official Documentation: Since there's no official documentation, detailed information about its parameters, behavior, and potential changes in different versions of SQL Server are not publicly available through Microsoft's channels.
  • Potential for Change: Microsoft may change or remove undocumented features in any new release or update of SQL Server without prior notice. This can lead to compatibility issues or sudden breaks in functionality in systems that rely on these features.
  • Limited Support: If you encounter issues while using undocumented features, finding solutions can be more challenging as these features are typically not covered by standard support channels.
  • Use with Caution: It's advisable to use undocumented features with caution, especially in production environments. They might be less stable or tested compared to officially supported features.
  • Alternative Approaches: For long-term stability and support, it's often better to seek alternative, documented features or methods to achieve the same goals.
  • Community Knowledge: Sometimes, information about undocumented features can be found through community forums, blogs, or from SQL Server experts who share their findings. However, this information is based on personal experiences and might not be universally applicable.


Usage Scenerios:


Here are a few example scenarios of how xp_sqlagent_enum_jobs might be used:

Basic Usage to List All SQL Agent Jobs

This is the simplest form of using xp_sqlagent_enum_jobs to get a list of all SQL Agent jobs with their details.

EXEC master.dbo.xp_sqlagent_enum_jobs 1, '<your_domain\your_login>'

/* OR */

EXEC master.dbo.xp_sqlagent_enum_jobs 1, 'sa'


Checking for Running Jobs

To check for currently running jobs using the TSQL, its more likely you would want to use the documented SP msdb.dbo.sp_help_job:

exec sp_help_job @execution_status = 1;

But just for sake of an example, you can use xp_sqlagent_enum_jobs to check if there are any jobs currently running on the SQL Server Agent.


IF OBJECT_ID('tempdb..#RunningJobs') is not null DROP TABLE #RunningJobs;
go
CREATE TABLE #RunningJobs (
    job_id UNIQUEIDENTIFIER NOT NULL,
    last_run_date INT NOT NULL,
    last_run_time INT NOT NULL,
    next_run_date INT NOT NULL,
    next_run_time INT NOT NULL,
    next_run_schedule_id INT NOT NULL,
    requested_to_run INT NOT NULL, -- boolean
    request_source INT NOT NULL,
    request_source_id sysname COLLATE database_default NULL,
    running INT NOT NULL, -- boolean
    current_step INT NOT NULL,
    current_retry_attempt INT NOT NULL,
    state INT NOT NULL
)


INSERT INTO #RunningJobs
EXEC master.dbo.xp_sqlagent_enum_jobs 1, '<your_domain\your_login>'
SELECT * FROM #RunningJobs WHERE running = 1

IF OBJECT_ID('tempdb..#RunningJobs') is not null DROP TABLE #RunningJobs;
go


Finding Jobs with Specific Conditions

You can filter the results to find jobs with specific conditions, like jobs that have failed to run, or jobs scheduled to run at a specific time.

SELECT * FROM #RunningJobs WHERE last_run_outcome <> 1 -- Replace with your specific condition


Wait for a SQL Server job to complete before proceeding


Precautions and Best Practices:


  • Use a Dedicated Account: When specifying the user account (<your_domain\your_login>), it's best to use an account with appropriate permissions.
  • Temporary Tables: In the examples, I've used temporary tables (#RunningJobs) to store the output of xp_sqlagent_enum_jobs. This is a common practice to make data handling easier.
  • Cleanup: Always remember to clean up temporary tables to avoid unnecessary consumption of resources.
  • Testing: Thoroughly test these scripts in a non-production environment first to ensure they work as expected in your specific SQL Server setup.
  • Monitoring and Logging: When using such procedures in scripts or applications, implement adequate logging and error monitoring.
  • Seek Alternatives: While I haven't tried or tested the following myself, here is an article discussing one of the possible alternatives:

xp_sqlagent_enum_jobs alternative


Tuesday, January 23, 2024

SQL Server's Buffer Cache: How to Calculate Dirty Page Sizes

SQL Server's Buffer Cache: How to Calculate Dirty Page Sizes

"Almost" everything SQL Server does happens through the buffer pool. Here, the buffer "pool" is a combinations of memory regions used by SQL Server. The largest and main region is the "buffer cache," which is why most discussions about SQL Server's inner workings, including performance issues and solutions, involve the buffer cache.

For example, if a query needs to read a page, it will be served from the buffer cache... if the requested page is not in there then it will be fetched from the disk into the buffer cache first, then served to the query. And if a query modifies a page, that too gets modified in the buffer cache first... then some other internal SQL Server processes will copy the modified pages from buffer cache to the disk.

Additionally, the buffer cache also contains data that doesn't yet exist on the disk (in SQL Server data files). This includes new data when it's added. Although SQL Server immediately writes this data to the transaction log file (unless Delayed Durability is enabled), it's not immediately written to the data files. Instead, SQL Server waits until the next CHECKPOINT process, which then writes these "dirty" pages to the data files. The LAZY WRITER process also writes dirty pages to the disk, but it does so continuously in a less aggressive manner.

There are exceptions though where SQL Server may bypass the buffer cache entirely and performs the direct disk I/O, for example for bulk load and bulk inserts.


Primarily, the buffer cache's job is to reduce the amount of time SQL Server spends reading data from the disk. It does this by keeping frequently accessed data in memory, which is much faster to access than disk storage.


Why size of dirty pages matters:


There are few reasons why you may want to track the amount and size of dirty pages in buffer pool, especially if it's too high as it is often an indicator of or contributes to slower performance, potentials of data loss and increased recovery and/or start up times.


Causes:

Some reasons I can think of top of my head are:

  • A simple and likely reason is that you have relatively high number of writes i.e. high number of INSERTS, UPDATES, and/or DELETES. Or that you have very large, long running transactions in progress, generating significant amount of dirty pages.
  • There is a memory pressure or more accurately the buffer pool is under pressure and can't write dirty pages to disk fast enough. This could be an indication that not enough memory is allocated to SQL Server or a more likely explanation is that your database needs a tuning.
  • The disk I/O is slow, i.e., the I/O subsystem is the bottleneck, causing a high count of dirty pages. Bluntly speaking, if you have slower disks, it can cause longer I/O queue length and a backlog of dirty pages waiting to be written to disk. Of course, the impact of slow I/O would be felt and manifested in several ways.
  • Heavy use of temporary tables can also cause high number of dirty pages
  • If the interval between checkpoints is too long then dirty pages can build up in the buffer pool. 


Calculating size of dirty pages:

To calculate the size of the dirty pages in buffer cache, SQL Server exposes some meta data regarding the pages in buffer cache through sys.dm_os_buffer_descriptors DMV.  Though I am not a fan, this still is the primary way to ascertain and monitor the size of dirty pages.

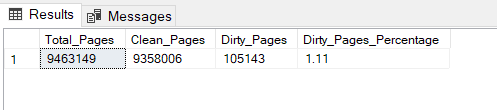
If you have VIEW SERVER STATE permission or, the SYSDBA role membership, you can query sys.dm_os_buffer_descriptors, mostly to get some summary information as it only contains the meta data. The below query is an example of such, which returns the ratio/percentage of dirty pages against the overall/total size of the buffer cache.

;WITH cte
     AS (SELECT Cast(Count(*) AS FLOAT) Total_Pages,
                Count(CASE WHEN is_modified = 0 THEN 1 END) Clean_Pages,
                Count(CASE WHEN is_modified = 1 THEN 1 END) Dirty_Pages
         FROM   sys.dm_os_buffer_descriptors
        )

SELECT Total_Pages,
       Clean_Pages,
       Dirty_Pages,
       Dirty_Pages_Percentage = Cast(( Dirty_Pages / Total_Pages ) * 100 
              AS DECIMAL(4, 2)) 
FROM   cte; 


Dirty Pages In SQL Server Buffer Cache


To get this information for each database:

;WITH cte
     AS (SELECT 
		database_id,
                Case When database_id = 32767 then '(ResourceDB)'
                     Else Coalesce(db_name(database_id),'***** TOTAL *****') 
                    End [Database],

		Cast(Count(*) AS FLOAT) Total_Pages,
                Count(CASE WHEN is_modified = 0 THEN 1 END) Clean_Pages,
                Count(CASE WHEN is_modified = 1 THEN 1 END) Dirty_Pages

         FROM   sys.dm_os_buffer_descriptors
         GROUP BY ROLLUP (database_id))

SELECT [Database],
       Total_Pages,
       Clean_Pages,
       Dirty_Pages,
       Dirty_Pages_Percentage = Cast(( Dirty_Pages / Total_Pages ) * 100 
              AS DECIMAL(4, 2)) 
FROM   cte
ORDER BY Total_Pages desc; 


A word of caution: if you have a very large buffer cache (like 750GB or even 75GB), querying this DMV can be very very slow. The larger the cache, the more data the DMV has to process. For a 75GB cache, it might need to process about ~10 million rows; for a 750GB cache, that number could jump to ~100 million rows!


Please also note that when using the sys.dm_os_buffer_descriptors tool to view the buffer cache contents, keep in mind that it also includes pages used by SQL Server's internal Resource database. Often, these pages are left out when people are summing up or analyzing the buffer cache data. However, in this particular example, I've chosen to include them in the count and analysis.

Alternative Method:

If you have huge buffer cache like 2TB or more, using sys.dm_os_buffer_descriptors can be impractical.  While not as detailed,  you can utilize the DBCC MEMORYSTATUS to get the size of dirty pages:


IF OBJECT_ID('tempdb..#MemoryStatus') IS NOT NULL
    DROP TABLE #MemoryStatus;

CREATE TABLE #MemoryStatus (
    ID INT IDENTITY(1,1) PRIMARY KEY,
    NAME NVARCHAR(100),
    VALUE BIGINT
);

INSERT INTO #MemoryStatus (NAME, VALUE)
EXEC ('DBCC MEMORYSTATUS WITH TABLERESULTS');

SELECT CASE WHEN NAME='Database' THEN 'Buffer Pages'
            WHEN NAME='Dirty' THEN 'Dirty Pages' 
		  ELSE NAME END NAME,
       VALUE / 128 SIZE_MB
FROM #MemoryStatus
WHERE NAME in ('Database','Dirty');


I would really prefer using windows performance counters for this but alas... there are no windows performance counters currently available that would measure size of the dirty pages.  There are some performance counters (e.g. Checkpoint pages/sec) can be used to get some idea about the size of dirty pages, I have though found them to be not adequate or accurate enough.  


Resources:


Using the DBCC MEMORYSTATUS command to monitor memory usage in SQL Server

sys.dm_os_buffer_descriptors


Wednesday, January 17, 2024

Best Practice Tip #1: Beware of Best Practices

Best Practice Tip #1: Beware of Best Practices

It may sound contractionary that the first item of a best practices list is to be wary of best practices. When you hear a piece of 'best practice' advice, it's wise to take a step back and think it through before jumping in.

Now, it's true that not every system is completely unique – there are times when systems are pretty much carbon copies of each other. But, each organization usually has its own set of specific needs and ways of doing things. There is no one-size fits for all, all the time. So, even if a piece of advice sounds good on paper, it's important to see if it really fits your particular situation.

Also, be wary of best practices that might be out of date. This includes tips for older versions of SQL Server or from the days when 8 GB of RAM was a lot. When you're searching online, you might run into advice that’s been hanging around for a while. Plus, a strategy that worked wonders for your system in the past might not be the best choice now if things have changed. And don’t forget, even if a tip seems like it'll boost your system, it could have downsides, like the risk of messing up things you've already done, which could be a major issue.


A Detailed Example:


Imagine you're managing your company's databases. You find this often-suggested tip: 'Always update to the latest database software for top performance and security.' It sounds sensible, and in fact, at my current job, it’s almost a given to keep everything up-to-date.

But here’s the catch: just because it's latest and greatest version doesn't mean it's automatically the right choice for you. It’s all about weighing the good against the potential hiccups. New versions might and often do offer cool features, but will they integrate smoothly with your current setup? Could they cause unexpected problems? It’s about finding the right balance for your specific needs. 


Here are few of the points to consider:


  • You have a database version that is stable and has been customized to suit your company's unique needs. Yes, this violates the best practice that don't change the default settings or deploy solutions that will get overwritten if you ever upgrade the version. But, here you are. And the latest database version offers new features, but it's unknown how these will interact with your customizations.
  • The best practices often do become outdated. Research if the advice is based on the latest information or if it was more relevant to older versions of the database software.
  • Analyze how the upgrade might affect your current workload and system performance.
  • Understand the potential risks, such as incompatibility with existing applications or downtime during the upgrade process.
  • While the upgrade might offer improved performance and security, it could also introduce new challenges or instability.
  • The risk of disrupting your current stable environment might outweigh the benefits of the new features in the latest version.


In any of the above circumstances, blindly following the best practice of upgrading to the latest software version without considering these factors could lead to unforeseen complications. 

Also, always test, test and test and have more than one back-out/rollback options ready in case things don't go as planned.

Here are some more examples:

  • Password Management: The old security best practice was to change passwords frequently, like every 90 days. This advise is now being questioned as it often leads to weaker passwords and password fatigue. The modern approach emphasizes strong, unique passwords possibly managed through a password manager, and the use of multi-factor authentication. MFA is already available in Azure SQL Server and, you could achieve this even in on-premise SQL Servers.
  • CPU, Memory and Storage Solutions: The use of physical servers for data storage and processing was a common practice. In today's cloud computing world, memory (both RAM and disk) and CPUs are not only cheap, they are dynamically available, and transient – therefore, not even a long-term investment if you don't end up needing them in future. 
  • Denormalization for Performance: In the past, full denormalization was a common practice to improve database performance, especially in data warehousing systems with limited resources. Nowadays, some or more degree of normalization is preferred. And I am aware, here I am dangerously close to long running debate/feud between the Team Star Schema Vs Team Snow-Flake Schema.
  • Vertical Scaling: The traditional approach to handling increased load or data volume was to scale up (vertical scaling) by upgrading the existing server's hardware (more CPU, RAM, storage). Modern databases often favor horizontal scaling (scaling out), which involves adding more nodes to the system (e.g., AlwaysOn Availability Groups), offering better fault tolerance and scalability.
  • Full Database Backups: In very distant past, relying solely on full database backups was common and/or the only option available, not anymore. While still important, it is inefficient for VLDBs. Incremental and differential backups are now frequently used alongside full backups to minimize data loss and recovery time.
  • Manual Tuning and Maintenance: Earlier, database administrators (DBAs) spent considerable time manually tuning queries and maintaining databases. Today, many databases incorporate automated performance tuning, real-time monitoring, and AI-driven optimization, reducing the need for manual intervention.


These examples illustrate how database management best practices have evolved and will continue to do so.


Tuesday, January 16, 2024

A Primer on Attaching Databases with PowerShell Method AttachDatabase

A Primer on Attaching Databases with PowerShell Method AttachDatabase

Attaching a SQL Server database using PowerShell can be straightforward. Here's an effective and easy approach using the Invoke-Sqlcmd Cmdlet, by encapsulating your SQL statement in a variable, and then pass it to the Invoke-Sqlcmd cmdlet. For example:


$sql_command = "

    USE [master]

    GO

    CREATE DATABASE [TestDB_20240115_173550] ON 

    ( FILENAME = N'K:\\SQL2022AG01\\DATA\\TestDB_20240115_173550.mdf' ),

    ( FILENAME = N'L:\\SQL2022AG01\\LOG\\TestDB_log_20240115_173550.ldf' )

    FOR ATTACH

    GO

"


Invoke-Sqlcmd -ServerInstance SQLVM01\\SQL2022AG01 -Query $sql_command


The above command assumes that the PowerShell module for the SQL Server is installed and imported into your PowerShell session.  For any DBA using PowerShell to manage SQL Server instances, I think this should be automatically loaded, which you can do by copying the SQL Server module files in one of the directories listed in $env:PSModulePath. 

To determine the locations where PowerShell modules can be stored, simply enter $env:PSModulePath in the PowerShell console and press Enter. This will display the paths:

PS C:\Users\Dummy> $env:PSModulePath

C:\Users\dummy\Documents\WindowsPowerShell\Modules;
C:\Program Files\WindowsPowerShell\Modules;
C:\WINDOWS\system32\WindowsPowerShell\v1.0\Modules

On my system, these three directories are where I can place PowerShell module files. The choice of directory depends on whether I want the module accessible only to my user profile or to all users on the computer. It also depends on my permissions to create files and folders in the Program Files and System32 directories.

You can verify if the SQL Server module is loaded into your current session with the Get-Module command. 

PS C:\Users\Dummy> Get-Module -Name sqlserver | Format-List

Name              : SQLServer
Path              : C:\Users\dummy\Documents\WindowsPowerShell\Modules\SQLServer\21.1.18256\SqlServer.psm1

Description       : This module allows SQL Server developers, administrators and business intelligence professionals to automate database development and server administration, as well as both 
                    multidimensional and tabular cube processing.
                    
                    For Release Notes, expand the Package Details section on this page.
                    
                    For automation with SSRS & Power BI Report Server, use the ReportingServicesTools module available at https://www.powershellgallery.com/packages/ReportingServicesTools
ModuleType        : Script
Version           : 21.1.18256
NestedModules     : {Microsoft.SqlServer.Management.PSSnapins, Microsoft.SqlServer.Management.PSProvider, Microsoft.AnalysisServices.PowerShell.Cmdlets, 
                    Microsoft.SqlServer.Assessment.Cmdlets...}
ExportedFunctions : {Invoke-SqlNotebook, SQLSERVER:}
ExportedCmdlets   : {Add-RoleMember, Add-SqlAvailabilityDatabase, Add-SqlAvailabilityGroupListenerStaticIp, Add-SqlAzureAuthenticationContext...}
ExportedVariables : 
ExportedAliases   : {Decode-SqlName, Encode-SqlName}


BTW,  in a layman's terms, a PowerShell module is basically your regular folder containing files like script files, DLL/assemblies files etc, as highlighted SQLServer value in the above example.

If it returns nothing that means you currently don't have the SQLServer module in your session. Generally, though if the module folder is in one of the folders listed in $env:PSModulePath then it should get automatically loaded into your session when you reference any of the commands from that module for the first time. PowerShell won't load a module into your session until it is required.

You can also manually load a module into your session using the Import-Module cmdlet:

Import-Module -Name sqlserver


If not then you can install it from the PSGallery, provided that PSGallery is configured as a repository:


Find-Module -Name SQLServer


Install-Module -Name SQLServer


Of course, I already have a previous version of this module installed, which I can upgrade to the latest version by adding -Force to the Install-Module command. This is also essentially how you would typically upgrade an existing module.


That being said, beyond SQL statements, PowerShell offers native cmdlets for database management. To attach a database, use the AttachDatabase method. Here's an example:


# Connect to the sql server instance
$sql_instance = Get-SqlInstance -ServerInstance SQLVM01\SQL2022AG01

# Attach the AttachDatabase method
$sql_instance.AttachDatabase('TestDB_20240115_173550', 'K:\SQL2022AG01\DATA\TestDB_20240115_173550.mdf')


The value for first parameter, "TestDB_20240115_173550", is the name for the attached database. The second value is the file path for the primary data file. SQL Server will look up the location of other files (secondary data files, transaction logs etc.) from the primary data file and will look for them in their original locations. 

Below is more information on the AttachDatabase method, along with the parameters you can pass to it. Notice the Definition field, each line in it starting with "void...." is called method/function overload  (https://en.wikipedia.org/wiki/Function_overloading)  , each has different list of parameters that SQL Server will automatically determine based on how you execute the method:

Get-Member -InputObject $sql_instance -MemberType Methods `
           -Name AttachDatabase | Format-List

TypeName   : Microsoft.SqlServer.Management.Smo.Server
Name       : AttachDatabase
MemberType : Method
Definition : void AttachDatabase(string name, System.Collections.Specialized.StringCollection files, string owner), 

             void AttachDatabase(string name, System.Collections.Specialized.StringCollection files), 

             void AttachDatabase(string name, System.Collections.Specialized.StringCollection files, 
                Microsoft.SqlServer.Management.Smo.AttachOptions attachOptions), 

             void AttachDatabase(string name, System.Collections.Specialized.StringCollection files, string owner, 
                    Microsoft.SqlServer.Management.Smo.AttachOptions attachOptions)


Lets look at the first function overload:

Void AttachDatabase(string name, System.Collections.Specialized.StringCollection files, string owner)


It accepts 3 parameters:

  1. Name: This would be the name of the database when it's attached
  2. Files: This would be an array with the database file names i.e. MDFs, NDFs, Transaction log files, FileStream directories etc. Only the location of the primary data file is required, rest are optional. If other files are omitted, SQL Server will read their location from the primary data file and then will try to look for them in their original location. If any of the files is missing, it will throw an error, and believe me, those error messages are not very informative!
  3. Owner: The name of the database owner. If you omit this value then the login of the current user will be the owner of the attached database. I generally use "sa" as the database owner.


Below is the second overload for the method. In this one you are not passing the value for Owner parameter.

 
void AttachDatabase(string name, System.Collections.Specialized.StringCollection files) 

Advanced Options: 


The method also supports AttachOptions for more control. Here is list of options you can pass to it:
  • EnableBroker
  • ErrorBrokerConversations
  • NewBroker
  • None
  • RebuildLog
For detailed information, refer to the Microsoft documentation:


In conclusion, PowerShell offers both straightforward and advanced methods for attaching SQL databases. Whether you prefer direct SQL commands or native PowerShell cmdlets, the process is efficient and well-integrated into the SQL Server environment. By understanding the nuances of these methods and ensuring the necessary modules are installed and loaded, you can seamlessly manage your SQL Server databases.